Once we have designed some basic differentially private algorithms, it is a natural idea to combine them and analysis the privacy loss. We begin with an illustrative example that sets up the mathematical model step by step.
Image yourself in front of the door of a safe vault protected by a password lock. To open the door, you need the correct password P. If tried with the wrong password, the lock would destroy itself automatically.
Luckily, you know two candidate passwords P1 and P2, with one of them being the correct one. Further, you notice that the designer of the lock left a collection of boxes near the door, which contain information on how they decide the correct passwords. Obtaining complete information of anyone of them gives you the correct password.
But the boxes are also protected and you don't have legally access to them. However, you can hack into the boxes. Hacking into the box won't give you all its information, but a random message. In particular, each box B is associated with a set RB, which is a finite collection of messages (in English). When B is hacked, it returns a message YB generated randomly from RB, whose distribution depends on the correct password P.
Let DB,P1 be the distribution of YB if the correct password is P1, and DB,P2 be the one if the correct password is P2. If there is a huge difference between DB,P1 and DB,P2, then you might be able to guess the correct password.
E.g., suppose RB= { "Dog bites.", "Cat scratches." } and the distributions are given as
DB,P1
DB,P2
"Dog bites."
0.99
0.01
"Cat scratches."
0.01
0.99
Hence, when you get YB= "Dog bites.", you prefer P1 over P2 and vice versa.
Anticipating such potential information leakage, the designer of the lock equips the boxes with a defense mechanism, called (ϵ,0)-mechanism. It guarantees the distributions DB,P1 and DB,P2 are similar so that it is hard for you to infer the correct password from the message. In particular, ∀S⊂RB, if S is measurable, it holds that
When these inequalities are satisfied, we say that DB,P1 and DB,P2 are (ϵ,0) close. The inequalities require DB,P1 and DB,P2 to have the same support on RB. Therefore, throughout our discussion below, we assume that both DB,P1 and DB,P2 assign positive probability to each element in RB. Otherwise, we can just replace RB with the support of DB,P1 (which is also the support of DB,P2).
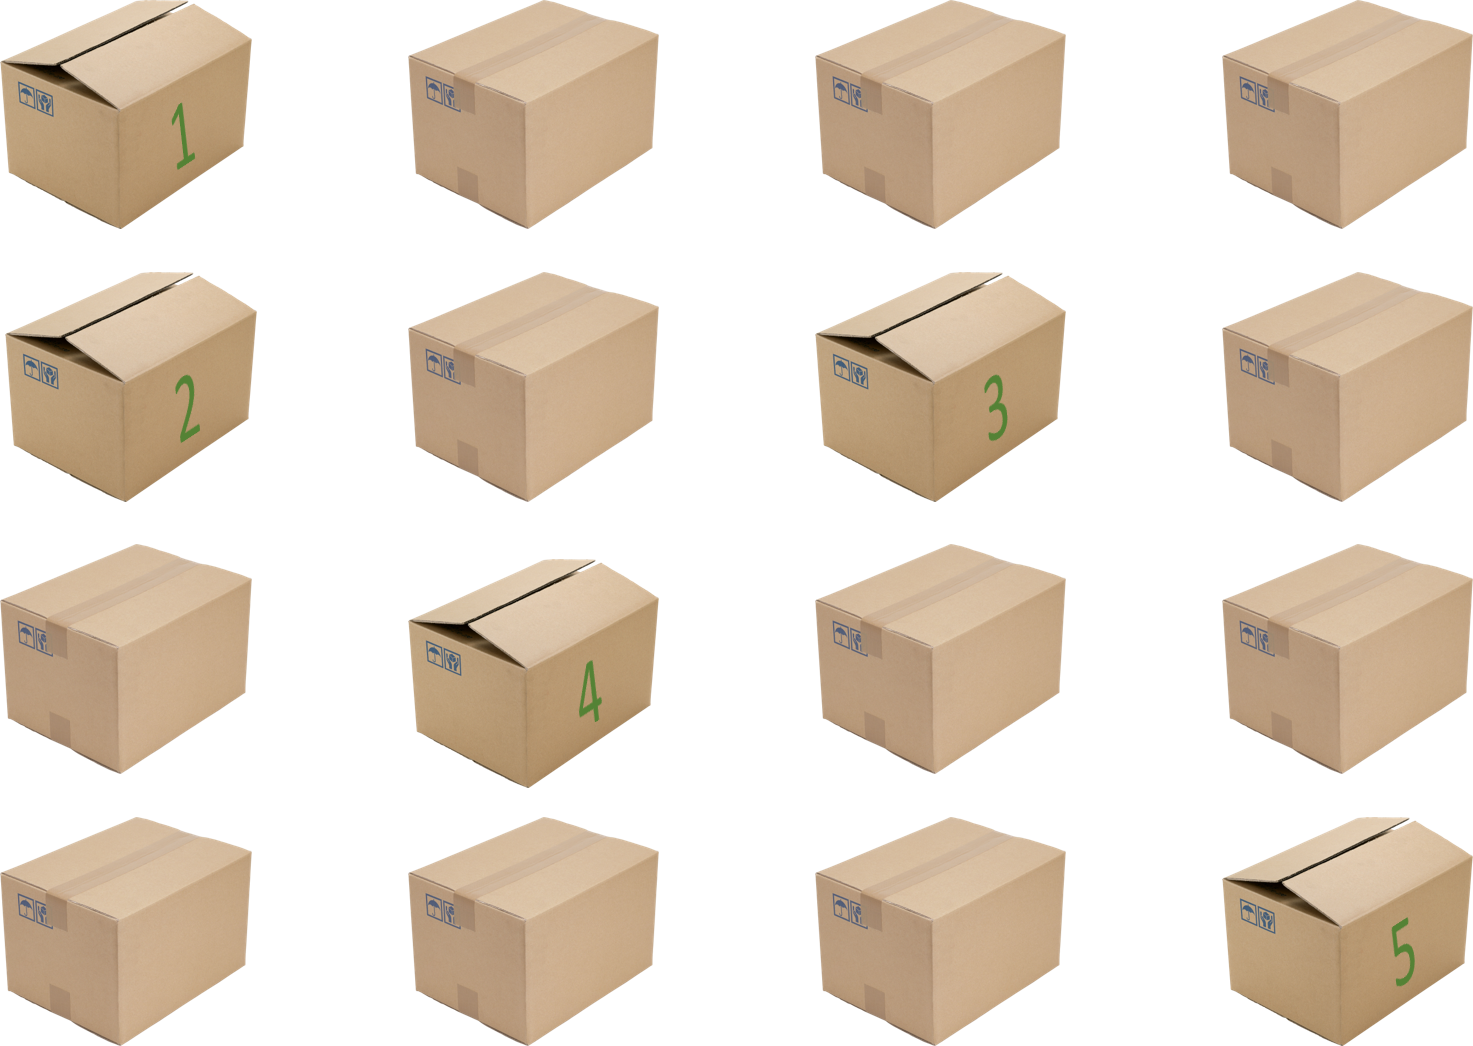
Now, hacking one box is unlikely to help you to guess the correct password. You want to hack more boxes, with the hope that the information combined will assist you. Due to resource limit, you can't hack all boxes but only a finite number of them. You choose the first box randomly. Then you choose every new box based on the information obtained from the hacked boxes. The figure below shows an example of hacking five boxes.
Suppose that your resource enables you to hack n boxes and let Yn=(Y1,Y2,...,Yn) be the output messages you obtained. Similar to the situation of hacking one box, if the distribution of Yn, conditioned on P=P1, is utterly distant from that conditioned on P=P2, then there could be some cases when you can confidently infer the true password. Conversely, to prevent severe information leakage, the designer needs to ensure there isn't such case, i.e., the two distributions should be similar.
What makes things even more complicated is that, the distribution of Yn depends not only on the output distributions of the boxes, but also on your strategy of choosing the boxes to hack. Let's use symbol A to denote your strategy. Whatever A is, the designer need to guarantee that the distribution of Yn conditioned P=P1 should be similar to that conditioned on P=P2.
Surprisingly, this is in some sense achievable, as long as for each box, its output distribution conditioned on P=P1 is (ϵ,0) close to that conditioned on P=P2.
Let R be the set of possible possible messages of all boxes.
If we view ϵ as the privacy loss of a single box, then the theorem states that the privacy loss grows to O(nϵ) is n boxes are hacked.
To prove the theorem, we need a rigorous model for the problem.
Definitions.
I: the index set.
{Bα:α∈I}: the collection of boxes.
{Rα:α∈I}: the ranges of the outputs of the boxes.
R≐∪α∈IRα: the range of any possible output by any box.
{Dα,P1:α∈I} ({Dα,P2:α∈I}): the set of output distribution when the correct password is P1 (P2). Without loss of generality, we assume that for a fixed α∈I, the distribution Dα,P1 (Dα,P2) assigns positive probability to each element in Rα. Moreover, Dα,P1 and Dα,P2 are (ϵ,0) close.
n: the number of boxes you can hack.
ik≐(i1,i2,...,ik): the index sequence of boxes you have chosen to hack up to time k, where k∈[0,n]. When k=0, i0 corresponds to a empty sequence.
Yk=(Y1,Y2,...,Yk): the random variables that represent messages outputted by the chosen boxes up to time k∈[1,n], where Yt∈Rit⊂R for t∈[1,k]. Therefore, Yk can be view as random vector in Rk.
xk=(x1,x2,...,xk)∈Rk: a point in Rk, where k∈[0,n]. When k=0, we define x0=∅.
hk=⟨ik,xk⟩=⟨(i1,i2,i3,...,ik),(x1,x2,...,xk)⟩: the history up to k∈[0,n], which consists of the chosen indexes and observations up to time k. We use h0 to denote the empty history.
A: your strategy (policy) for choosing boxes. It works as follows: for any fixed history hk=⟨ik,xk⟩, A is associated with a fixed distribution DA,hk over I∖ik, the set of indexes of the unchosen boxes. When inputted with hk, A returns a random variable A(hk) that follows the distribution DA,hk.
We will show that, no matter what strategy you use, it is unlikely that you distinguish via the output Yn whether the correct password is P1 or P2. This is because whether P=P1 or not, the output distributions of Yn are similar.
Proof of the theorem. We will just prove the first inequality, and the second one follows from symmetry. We consider a bad set in Rn:
Fact 2. (Azuma Inequality). Let C1,....,Cn be random variables such that ∀k∈[n], Pr[∣Ck∣≤ϵ]=1, and for every (c1,...,ck−1)∈Supp(C1,...,Ck−1), we have
E[Ci∣C1=c1,...,Ck−1=ck−1]≤β,
Then for every z>0, we have
Pr[k=1∑nCi−nβ>z]≤exp(−2nϵ2z2)
Finally, applying Azuma Inequality with z=2nlogδ′1 and β=(eϵ−1)ϵ, we get the desired result.
■
Reference.
[1] C. Dwork and A. Roth, “The Algorithmic Foundations of Differential Privacy,” Foundations and Trends® in Theoretical Computer Science, vol. 9, no. 3–4, pp. 211–407, 2013